Prompt Engineering

Prompt engineering is the practice of designing and refining the input — the "prompt" — you give to an AI system to get the output you want. An AI model,  like a large language model or image generator, can't read your mind or do subtle interprations of language. It predicts what should come next based on the words, structure, and context you give it. Prompt engineering is learning how to shape that context deliberately.

I have a friend who teaches prompt engineering. He is in an university engineering school, but he says that in practice, it's less "engineering" in the formal engineering sense, and more applied communication. It is about figuring out how to be explicit enough that the model doesn't have to guess, without burying it in so much text that it loses the point. It is also less of a full course and more likely a component of a course.

MIT's OpenCourseWare / MIT Sloan offers short courses like "Prompt Engineering and Advanced ChatGPT" in their professional programs. Vanderbilt on Coursera is a good starting place because it's free to audit, self-paced, and built by a university. Here in New Jersey, my alma mater Rutgers, former employers NJIT and Montclair State University, and Stevens Institute list prompt engineering workshops or modules inside Computer Science, Business Analytics, and Continuing Education/workforce development programs. These might be a 1-2 day non-credit certificate, or a unit in "Applied Generative AI."

Looking at a few of these courses, you find some commonalities in what needs to be learned.

Create the prompt's instructions - what you actually want done. Vague prompts get vague results. "Write about terms of service" is vague and weak. One more specific prompt might be "define browsewrap agreements in 150 words for a non-lawyer, compare them to clickwrap, and give examples of why courts find them unenforceable."  I used that prompt in writing my earlier post on terms of service.

A good prompt includes context and constraints by giving a role, audience, format, and rules to follow.
Role: "You are a tech journalist..."     Audience: "...explain it to a college freshman"    Format: "use a table with 3 columns"    Constraints: "no legal advice, keep it under 200 words"

Some methods people use to get more reliable reasoning:
Zero-shot vs. few-shot: Show 0 examples vs. show 2-3 examples of input/output
Chain-of-thought: "Think step by step" to make it show its reasoning
System vs. user prompts: System = persistent rules, User = the specific task
Iteration: Test, see failure, add a clarification, test again

I compare much of this to when I was teaching younger K-12 students in the late 20th century about doing Internet searches. The Internet started in higher education, then took about two decades to get to K-12 in a meaningful way. In higher ed, there were significant inroads in the early 1990s with the Web and browsers, although some select schools were using it in limited ways starting in 1969. For K-12, it happened around 1996-2000, driven by the E-Rate, making the late 1990s/early 2000s when the Internet went from a lab curiosity to a daily classroom tool.

My students were using it for research papers and needed to be taught about the same kind of specificity. Assigned to write about why women were not allowed on stage in Shakespeare's time, they might type "women in Shakespeare" and get hundreds of hits about female characters in the plays. In the late 1990s, search engines were not sophisticated enough to handle a query such as "why were women not allowed to act on stage in Shakespeare's time and how did acting companies adapt to this?" Today, it can use that query/prompt. And that is something that frustrates many teachers and delights their students.
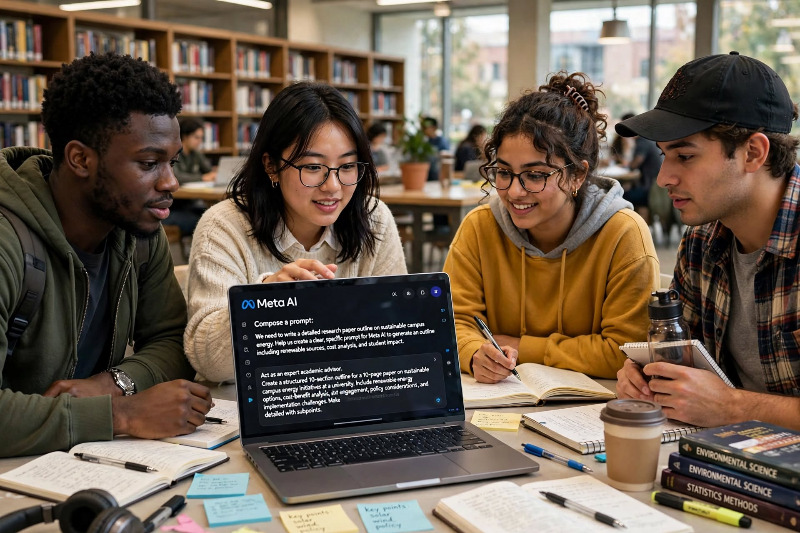
students using prompts

Is The World Still Flat or Even Flatter?

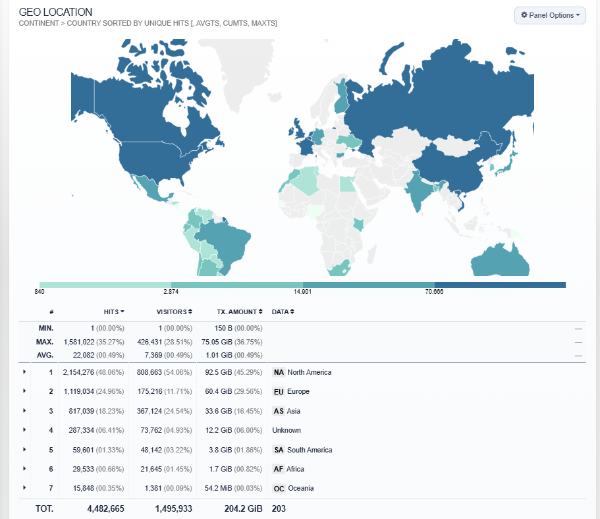
I was looking at the analytics for this blog, which includes the countries that have visited its pages. It is quite global. That got me thinking back to a book that made a big splash in 2005.


Thomas Friedman's The World Is Flat: A Brief History of the Twenty-First Century was published in 2005. It was updated as 2.0 in 2006 and 3.0 in 2007.

What he said originally was that the world is becoming "flat." The competitive playing field between developed and emerging economies has been leveled, so individuals and small companies can compete globally like never before. He called this Globalization 3.0.

Globalization 1.0 (1492-1800) was driven by countries. Globalization 2.0 (1800-2000) was driven by multinationals. The 3.0 version was driven more by individuals empowered by technology. A trip to Bangalore made him realize work could be done anywhere.

He desribed 10 "flatteners" that made it possible.

  1. November 1989 Berlin Wall falls, plus Windows and the end of Cold War, while PCs are creating more and more content
  2. August 1995 Netscape IPO — the web for everyone
  3. Workflow software — SMTP, HTML, standards letting machines talk to machines
  4. Uploading — open source, Wikipedia, blogs combined are the "most disruptive force of all"
  5. Outsourcing — splitting work to the cheapest, most efficient place
  6. Offshoring — moving factories to China after WTO entry 
  7. Supply-chaining — Wal-Mart style global logistics 
  8. Insourcing — e.g. UPS repairing Toshiba computers 
  9. Informing — Google, search — anyone can find anything 
  10. The Steroids — wireless, VoIP, file-sharing making it all mobile, digital, personal

book cover
How has he revised it since?

Friedman himself did two early revisions — the 2006 edition was explicitly to answer critics and readers, especially about education. Since then, in interviews, columns, and his 2016 book Thank You for Being Late, he has shifted in four ways.

From flat to fast, fused, deep, open, he now says the world is not just flat; it is also fast, fused, deep, and open due to accelerating technology. Later: fast, fused, deep, and fragile — acceleration in technology, globalization, climate, and debt is exponential.

He admits he underestimated the downside. The original was a techno-optimist. Critics like Pankaj Ghemawat showed 90% of traffic was still local, Joseph Stiglitz said the world was getting less flat for many, and geographers called it "spiky." Friedman now talks much more about inequality, the hollowing out of middle-class jobs from outsourcing/offshoring, and political backlash (Brexit, Trump, anti-globalization populism). He said after 2008: "The world is even flatter than I thought. Our mortgage crisis is killing Deutsche Bank."techno-optimistic

The safety net argument got stronger. Originally it was learn new skills. Now it is tat society needs lifelong learning, portable health/retirement benefits, community anchors, and government help for transitions. (This is the core argument of Thank You for Being Late)

His Dell Theory of Conflict Prevention (AKA simply the Dell Theory) is an updated version of his previous "Golden Arches Theory of Conflict Prevention". According to Friedman, Dell Theory stipulates: No two countries that are both part of a major global supply chain, like Dell's, will ever fight a war against each other as long as they are both part of the same global supply chain. He has since acknowledged that supply-chain interdependence didn't prevent Russia's war on Ukraine, US-China decoupling, or COVID supply-chain collapse. Interdependence raises the cost of war but doesn't prevent it. The lesson became resilience, not just efficiency — you need "just in case" as well as "just in time."

So what does this have to do with this blog?

Well, the flattener of "uploading" (open source, Wikipedia, blogs combined) is still disruptive. If I were writing these posts on some 1980s print media platform, the audience would never have the reach it has here. Actually, I would likely never have been allowed to write in those places. 

If Friedman decides to do a version 4.0 revision, he certainly would need to include artificial intelligence, which affects all of his original flatteners in some way. 

Terms of Service

terms illustrationRecently, I received notice from the music service Spotify that "We are updating our Terms of Use to make some updates to the dispute resolution provisions, including the Arbitration Agreement. You can read them  here." It is dense, and like many users, I gave it a cursory read-through and agreed. That is not the smartest thing to do, but I am hardly alone in doing it. In fact, some companies rely on that attitude. When users have been surveyed about their issues with terms of use/service, the same themes seem to always appear.

1. Most ToS run thousands of words in dense legal language. You wonder if that is not deliberate so that you DON'T review them but just quickly agree. One study found average users could answer only 40% of questions about an agreement they had just studied, and about 70% of people don't read them at all because they assume it's boilerplate. This is known as clickwrap, because you must take an affirmative action — click "I agree," check a box, or click "Accept" before you can proceed. Courts like this because there's clear proof you saw the terms

2. Why would you just agree to terms you haven't read? Because you can't negotiate. If you want to use the app, website, or device, you have to click "I agree." With "browsewrap agreements," you may be bound just by continuing to use a site, without ever seeing the terms. A browserwrap (AKA browsewrap) agreement is the most passive kind of online contract. It's the link you see at the very bottom of a website that says "Terms of Use" or "Privacy Policy." The site is claiming something like, "By just using this website — browsing, scrolling, downloading — you agree to our terms, even if you never clicked anything or read them." No "I Agree" button, no checkbox, no pop-up. Consent is implied by continued use.Courts often don't like them. (see note at bottom)

3. One-sided rights where the terms protect the company, not users. That might include language such as this:
Company can change the service, remove features, or delete your content/account at any time.
Purchases (especially digital goods, games, virtual items) are non-refundable and can be altered.
Company keeps broad license to use what you post

4. Some data and privacy items are hidden in the language. You click agree and later learn you consented to data collection, data sharing with third parties, tracking, targeted ads, and AI training on their content. The concern is trading away information and legal rights in a binding contract without realizing it.

5. Further, there may be legal rights you give up without noticing. Some common clauses:
mandatory arbitration and waiver of class-action rights
limits on liability if the service harms you or loses data
choice of law/venue far from where you live

6. Term can also change quietly and some companies reserve the right to update the terms at any time. Users aren't always notified clearly, so the rules you agreed to last year aren't the rules today.

7. Because the language is often deliberately vague, users aren't sure what will get them banned, demonetized, or suspended, or how appeals work. That leads to the feeling that enforcement is arbitrary.

Courts often don't like browsewrap 
because users generally don't know they're in a contract. A website is purporting to bind you by passive conduct unrelated to the terms themselves, like continuing to use the site. For that reason, U.S. courts have generally enforced browsewrap agreements only in limited cases — for example, against knowledgeable businesses — not against everyday individuals who had no reason to know the terms existed. To be enforceable at all, courts now look for two things: 1)  Conspicuous notice — Is the link to the terms placed where a reasonable person would see it, not hidden at the bottom in small light-gray text?  2) Actual or constructive knowledge — Did the user have reason to know the terms applied? This may also apply to what is known as the hybrid "Sign-in-wrap" that might read "By signing up, you agree to our Terms" next to the sign-up button.


An Estonian Approach to Chatbots in Schools

illustrationThe use of AI in schools is a big topic right now in the U/S. and probably in most of the developed world.

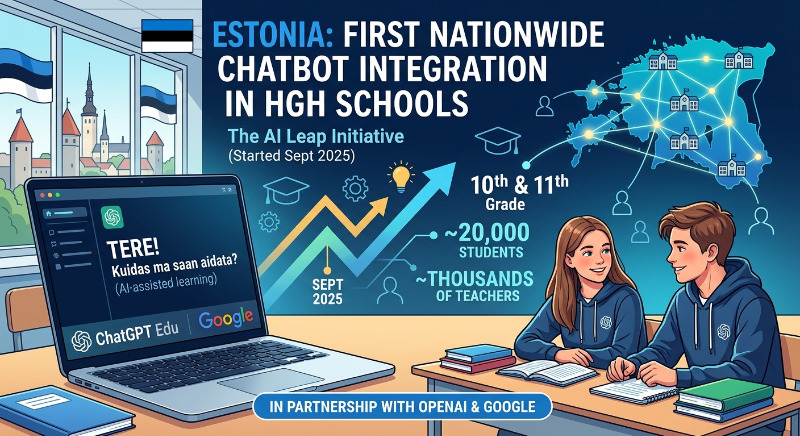
Estonia is the first country to integrate a customized chatbot nationwide across its high school system, moving away from bans to embrace AI-assisted learning.

The AI Leap Initiative began in September 2025 for 10th and 11th-grade students, reaching nearly 20,000 students and thousands of teachers. They partnered with OpenAI to use ChatGPT Edu and Google.

What is quite different about this version of a chatbot is that ChatGPT Edu uses the Socratic method. Instead of writing essays or giving direct answers, the customized AI acts like a coach. It guides students through problem-solving, reasoning, and critical thinking by asking questions rather than answering their questions.

That is an approach that will seem strange and probably frustrating at first to a user who is used to the reverse model. If the student asks "Why does the sky appear to be blue?" the response may be "What is your best guess at why it appears blue?"

Teachers receive premium access to AI tools for lesson planning, administrative tasks, and reducing workload, alongside professional "study circles" for training.

Estonia may seem to Westerners to be an odd choice for this experiment. I would not be surprised if an American had no idea where Estonia is located. Estonia, officially the Republic of Estonia, is a country in the Baltic region of Northern Europe bordered to the north by the Gulf of Finland across from Finland, to the west by the Baltic Sea across from Sweden, to the south by Latvia, and to the east by Russia. OpenAI noted that Estonia is already among the top 15 countries globally for ChatGPT usage. They have one active ChatGPT account for every four citizens, and aggregated usage data shows Estonians use ChatGPT primarily for tutoring and teaching, computer programming, and writing.

https://openai.com/index/estonia-schools-and-chatgpt/